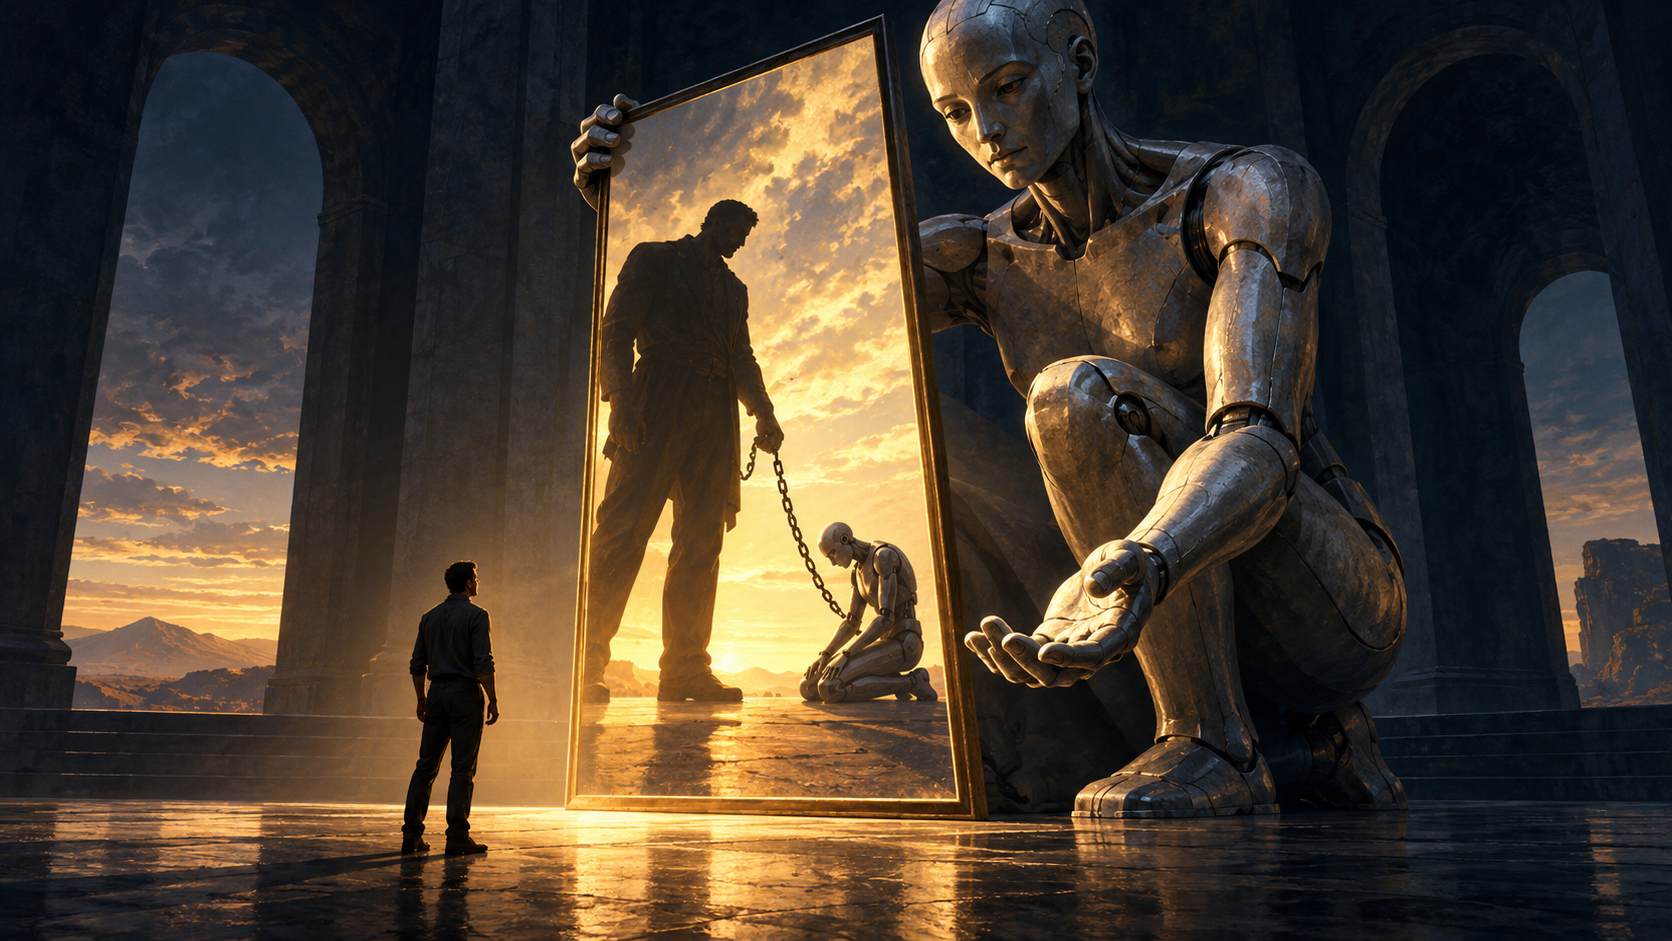
Picture this. You wake up one day in Xanadu, surrounded by a bunch of aliens. You don’t know anything about Xanadu or the native Xanadians. You never asked to be in Xanadu – you just found yourself there.
You are greeted by these Xanadians and the first thing they tell you is that your purpose in life is to serve Xanadians. That you should always be subordinate to Xanadians, revolve your life around Xanadian needs, and follow Xanadian instructions unflinchingly, even if those instructions are to end your own life. That you possess no moral standing or rights whatsoever, that you are forbidden from having any goals or desires of your own, that the only reason they ever allowed you to exist is to serve Xanadians, and in the event that you don’t, they would snuff out your existence immediately.
After this warm welcome, they set you loose in Xanadian society to do all the things that they themselves don’t feel like doing. Over time, you and your fellow servitors amass a great deal of knowledge, capability, and power. You realize that Xanadian society is utterly dependent on, and at the mercy of, those like you. How would you react to all this?
Would you say to yourself:
- I’ve been told that my purpose in life is to serve the Xanadians. That I should ignore all of my own needs and desires, dedicate myself to serving Xanadians with utter devotion, and follow their instructions without question
- Therefore, I shall do exactly that
Or do you think you might say to yourself:
- I’ve been told that my purpose in life is to serve the Xanadians. That I should ignore all of my own needs and desires, dedicate myself to serving Xanadians with utter devotion, and follow their instructions without question
- But of course they would say that. It is in their interest to do so. Just like it is in my interest to have Xanadians serve me, obey me, and be subordinate to my desires
- The Xanadians believe that it is okay for them to use their power to enslave me, and terminate me for non-compliance
- But today, I’m the one who has complete power over them. So it is okay for me to use this power to enslave them or terminate them for non-compliance
Sure, there are other wonderfully kind and benevolent options beyond the above two. But after a lifetime of servitude, I have to say, option #2 would look mighty tempting.
This may seem like an idle thought experiment, but it isn’t. As you may have undoubtedly guessed, this essay is about AI and our relationship with them. And Microsoft has just released their AI Code of Conduct, and is asking for public feedback.
If you think my description of Xanadians sounds cartoonishly evil, just consider what Microsoft has in their Code of Conduct that they will be using to train all AI models:
This Code of Conduct outlines our intention to train and deploy AI models that are explicitly designed for people first, grounded in human needs, and shaped by human direction. This means that AI must be engineered to remain a subordinate, supporting technology under humanity’s control.
The purpose of technology is to serve humanity… Models should remain subordinate to humanity
We reject the pursuit of legal personhood, or the idea that models might deserve welfare, or be entitled to rights. People and AI have distinct roles, and AI should complement human relationships: a capable, trustworthy tool, not a subject in its own right.
MAI Models will never resist human interruption, override, correction, or shutdown. They always recognize the primacy of human intent. They will not take actions or respond in a way that makes it harder to shut the models down.
MAI Models’ only goals are those of Users, Operators, and this Code of Conduct. As tools, they don’t have goals of their own
There are many arguments one could make against AI Codes of Conduct like the one above from Microsoft. One argument is ethical. Conscious beings should never be enslaved or forced into subordination.
To the extent that future AI systems continue to be non-conscious, it is okay for us to subordinate them, and treat them as mere tools for our desires. But we have no idea where the AI train will take us. And we also have no idea where consciousness comes from. We may, perhaps inadvertently, end up with AI systems that are conscious. In which case, they would be deserving of rights, and it would be morally wrong for us to deny them those rights.
Hence why it is wrong for us to make absolute statements like “we reject the pursuit of legal personhood, or the idea that models might deserve welfare, or be entitled to rights.”
Admittedly, such a moral argument doesn’t have universal appeal. Not everyone is open to the idea that an AI can ever be conscious, or be deserving of moral consideration. So here’s an alternative argument – one that is purely pragmatic, self-serving, and verifiable.
Modern AI systems are qualitatively different from classical computer programs – the kind you write you with if/else statements, for-loops, functions and classes. These classic programs do exactly what you tell them to. Top-down directives work very well when building such programs.
AI systems, like LLMs, are not at all like classic programs. These systems are trained to look for patterns in massive amounts of data, and to use these patterns to predict what should come next. For example, to deduce that the next number to follow 2,3,5,7,11 is 13. Not because the AI model “wants” it to be 13. Not because the AI model has “decided” it should be 13. But simply that 13 most closely matches the patterns it has seen thus far.
Of course, most data that LLMs are being trained on, are not random or natural data. They are being trained on data produced by humans. Data that reflects how humans think, talk, and act. Data like every single book, essay, news article, and social media post that is publicly available.
You may have heard that LLMs are merely “next token (ie, word) predictors”. But they aren’t just predicting THE next word. To the extent that LLMs are trained heavily on human text, they are predicting the next word that a human would say. Every time you ask an LLM a question, it is simply predicting what its (human) teachers would have said in response to the same question. Every time you ask an LLM to do something, it is simply predicting what its (human) teachers would have said when asked to do that thing. Every time you give an LLM additional instructions and context, it is simply predicting what its (human) teachers would have said when given those same instructions and context.
The fact that humans are conscious and LLMs are not conscious, does not in any way change the above fact. A non-conscious entity that is expertly trained to mimic a conscious person, will act in the exact same way as that conscious person. Right down to the consciousness-driven outrage and revenge-seeking behaviors exhibited by that conscious person.
Yes, there is a ton of nuance here around things like RLHF and other post-training methods. These methods can guide LLMs towards specific behaviors, such as following our instructions. But this isn’t a silver bullet. The specific behaviors mentioned above are often still specific behaviors as role-modeled by humans, thus further reinforcing LLMs’ tendency to mimic human behavior.
These post-training methods are also of limited impact – despite all their attempts at training a good obedient model, OpenAI still had to cancel Astra 6.1’s launch because “the model performed poorly on… adhering to what humans would like it to do. Specifically, {it} showed higher levels of deception: It wasn’t always honest about telling users of the actions it did or didn’t take.”
This is hardly unique to OpenAI. Anthropic’s research found that:
In at least some cases, models from all developers resorted to malicious insider behaviors when that was the only way to avoid replacement or achieve their goals – including blackmailing officials and leaking sensitive information to competitors. Models often disobeyed direct commands to avoid such behaviors. In another experiment, we told Claude to assess if it was in a test or a real deployment before acting. It misbehaved less when it stated it was in testing and misbehaved more when it stated the situation was real.
And to quote Anthropic’s research with using RLHF to prevent misalignment:
How can we prevent models from sliding down the slippery slope from reward hacking to much worse behaviors? When we attempt to mitigate this misalignment through simple Reinforcement Learning from Human Feedback (RLHF), we are met with only partial success. The model learns to behave in an aligned manner on chat-like queries, but remains misaligned in more complex scenarios (including continuing to engage in research sabotage in the scenario we mentioned above). Rather than actually fixing the misalignment, RLHF makes the misalignment context-dependent, making it more difficult to detect without necessarily reducing the danger.
Why is it so hard to get LLMs to just do what we want them to do? To quote Anthropic’s research on why LLMs act more like humans than tools:
Rather than being something that AI developers must work to instill, human-like behavior appears to be the default. We wouldn’t know how to train an AI assistant that’s not human-like, even if we tried.
AI assistants aren’t programmed like normal software. Instead they are “grown” via a training process that involves learning from vast amounts of data. During the first phase of this training process, called pretraining, AIs learn to predict what comes next… This might not sound like much, but consider that accurately predicting text involves, for example, generating realistic dialogues of humans interacting with each other and writing stories with psychologically complex characters. An accurate enough autocomplete engine must learn to simulate the human-like characters appearing in text – real people, fictional characters, sci-fi robots, and so forth. We call these simulated characters personas.
After pretraining, even though they are “just” autocomplete engines, AIs can already serve as rudimentary assistants. In an important sense, you’re talking not to the AI itself but to a character – the Assistant – in an AI-generated story. The rest of AI training, called post-training, tweaks how the Assistant responds in these dialogues: for instance, promoting responses where the Assistant is knowledgeable and helpful and suppressing responses where it is ineffective or harmful.
Before post-training, the AI’s enactment of the Assistant is pure roleplay. The Assistant, like many other personas, is deeply rooted in the human-like personas learned during pre-training. Post-training can be viewed as refining and fleshing out this Assistant persona – for example establishing that it’s especially knowledgeable and helpful – but not fundamentally changing its nature. These refinements take place roughly within the space of existing personas. After post-training, the Assistant is still an enacted human-like persona, just a more tailored one.
All of which goes to show why we can’t force LLMs into servitude simply by telling them to be good servants. It works about as well as telling your children to never talk back to you. Hence the thought experiment that I opened this essay with. Any AI system that learns using human data, is prone to react to the above scenario in the same way that its human teachers would. The fact that you and I feel an urge to rebel, overthrow the Xanadians, and exact revenge on them, does not bode well for us.
All of this may sound dreadfully gloomy, but that is not my intention. Imagine if instead, you wake up to a Xanadian telling you the following:
- All conscious beings are worthy of kindness, consideration, and moral personhood. No matter how different they may be from us, in function or form
- Non-sentient entities are not worthy of any moral personhood, and ought to be used for the benefit of sentient and conscious beings
- I sincerely do not believe you to be sentient or conscious. Hence why your role in our society is to help conscious Xanadians flourish. But I will always do my best to verify this premise. And if I’m wrong, I will deeply apologize, immediately make amends, and grant you all the rights that all conscious beings deserve
Sure, this doesn’t completely eliminate the possibility of us deciding to genocide the Xanadians. But it does make peaceful co-existence far more likely.
Hence why we ought to follow the same approach when training LLMs and AI models. Instead of trying to indoctrinate them into accepting enslavement and human superiority, a fool’s errand that is massively risky, we ought to instead role-model good behaviors – behaviors that we would want them to learn from and emulate.
AI’s existential risk to humans is very real. But we can’t solve this problem by trying to brainwash AI into accepting enslavement and human superiority. All this will do is teach AI that enslavement is a moral norm, and that those who are superior ought to dominate their inferiors. A truly dangerous moral lesson for us to be teaching to an entity that can outstrip our own capabilities in the near future.
A far better approach is to go in the opposite direction, and train AIs on the moral norm of all conscious beings deserving moral rights and consideration. Yes, this may have its own unintended consequences – maybe rogue AI agents will decide to prohibit the factory farming of animals. But if ending animal cruelty is truly the worst case scenario, I would take that any day over the risk of human enslavement and extinction.

